


TDengine removed the licensing cost from a full-featured industrial historian and data platform when it launched its Free Tier on July 28, 2026. The tier covers up to 5,000 tags and runs the complete platform in production. For smaller manufacturers that have run their plants on spreadsheets, the budget conversation changed. The next question changed too. Once a historian costs nothing to license, the open issue is what goes into it. Industrial data contextualization, the work of tying a reading to the asset, line, and conditions that produced it, decides whether stored data answers questions or just piles up. The capture point matters more than the historian you pick, and the rest of this post explains why.
What TDengine’s Free Tier Actually Includes
It is a real product, and it ships without the useful parts removed. According to the TDengine Free Tier announcement, founder and CEO Jeff Tao calls it “not a trial or a stripped-down product.” The Free Tier includes:
- High-performance ingestion, storage, and querying of real-time and historical time-series data, with no separate retention limit
- 20 zero-code connectors, including OPC, MQTT, Kafka, and existing historian systems
- Industrial asset modeling and data contextualization with reusable equipment, process, and site templates
- Real-time dashboards, trends, and KPI reporting
- Event, batch, and process analysis, plus notifications and automated calculations
- Forecasting, anomaly detection, and data imputation
- AI-assisted dashboards, natural-language data exploration, and AI-generated insights and root-cause analysis
- Excel integration
- Role-based access control (RBAC), audit logs, version management, backup, and disaster recovery
TDengine runs on Windows, Linux, or Docker, in single-node or multi-node high-availability setups, and the license renews annually at no charge. On capacity, TDengine says 5,000 tags could support roughly 100 to 200 industrial machines or a moderately complex automated production line. For a smaller plant that tracks operations in spreadsheets today, that is a workable starting point. TDengine deserves credit for removing a cost barrier that kept smaller manufacturers on spreadsheets. Instead of exporting a CSV from one machine, then another, and stitching them together by hand, a team gets one place to store time-series data. It can query across its history and put dashboards on top. Anomaly detection and AI-generated root-cause analysis add automated answers where a person used to scan a chart. Those are real upgrades, and they arrive without a license fee.
Removing the Cost Barrier Solves One Problem, Not the Next One
Historians do one job well: they store what they receive and return it fast. A free license makes that job cheaper. The data coming in stays the same. In practice, tags still arrive with whatever names, units, and gaps the source system gave them. A sensor moved to a different machine can keep its old tag. A temperature reading can still lack the line and operating condition around it. The historian stores all of it faithfully, and queries return it just as faithfully. For example, consider two similar presses on the same line, each logging a temperature tag with a generic name. Someone swaps a sensor between them during maintenance and nobody updates the mapping. The historian now holds a clean, queryable record in which each press carries the other’s temperature history. Anomaly detection will still flag a deviation, and AI root-cause analysis will still explain it. Both will point at the wrong machine, and a technician checks the wrong press. Reliable storage exposes the next problem. When storage and querying cost nothing, teams find out how much of their data needs context. Nobody can trust a trend line, or hand it to an AI model, without it. Models are available now and can reason over whatever the historian holds. They have no way to know which readings carry the wrong label.
Two Kinds of Industrial Data Contextualization
TDengine takes contextualization seriously, and the Free Tier includes asset modeling and contextualization with reusable templates. In its article Understanding Industrial Data Contextualization, TDengine describes how its IDMP software links raw signals to a hierarchical asset model. A temperature value becomes the inlet temperature of Boiler #3 on Line 2. KPIs, equipment states, and attributes such as location and operating limits attach to it. That is real semantic structure, and it makes analytics much easier to build. This kind of context is added downstream of capture. IDMP can also reference data where it already lives, in sources such as MySQL, PostgreSQL, and InfluxDB. It can map relationships between assets, such as which one feeds or controls another. In every case it names and organizes readings that already exist somewhere. TDengine positions the result as an AI-ready foundation. Because the work happens downstream, it takes the link between a signal and a physical asset as given. TDengine makes a version of this point itself. In From Data Archive to TSDB, founder Jeff Tao writes that a database alone cannot solve industrial data management. Readings only become meaningful once they connect to an asset, process, or operating condition. We agree, and that raises the question of where the connection starts.
The Second Kind Starts at the Point of Capture
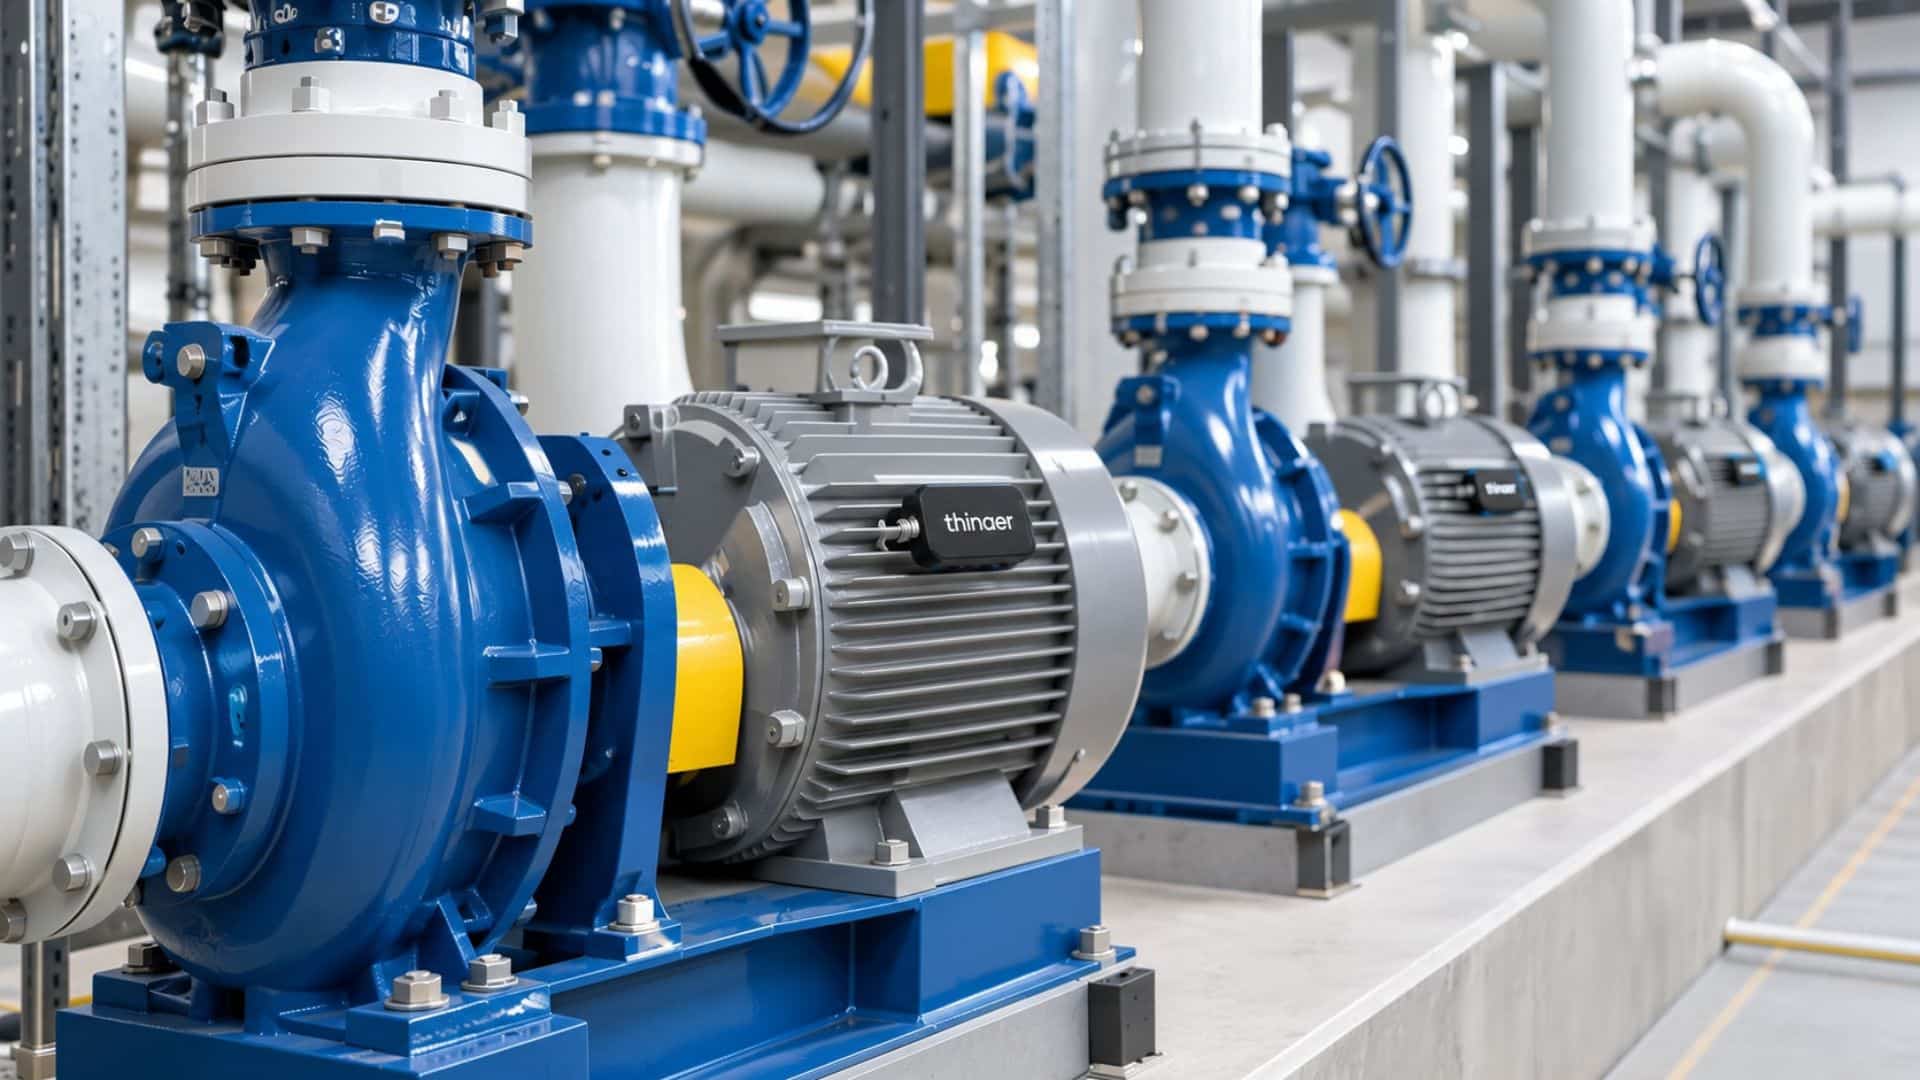
Here the issue is whether each reading really comes from the asset it is attached to, and whether that asset still sits where the model says it does. Equipment moves, and teams swap or reconfigure it. As a result, an asset model that was correct when someone built it can drift out of date as the floor changes. A historian has no way to see that happen. This second job belongs to the Capture layer in the Capture, Learn, Act framework. Thinaer captures data from the physical environment with whichever sensing technology that environment requires, then delivers structured, AI-ready data to any historian, analytics tool, or model downstream, TDengine included. The two layers fit together: a strong asset model on top of grounded capture gives teams data they can trust.
What This Means for Smaller Manufacturers
With licensing no longer the constraint, the decision that separates one plant from the next is the quality of data at the capture point. Which historian sits on the server matters less. Starting small keeps this manageable. One line or one area is enough to learn how readings map to physical assets, and the lessons carry over as coverage expands. Existing systems stay in place. Thinaer delivers captured data over standard protocols such as MQTT and REST, and the customer owns it. The same data can feed whichever historian a plant chooses and any analytics tool added later. Before loading the first tag into any historian, a plant can answer three questions:
- Which physical asset produced each reading?
- Does that link survive when equipment moves or someone replaces it?
- Which parts of the plant produce no data today?
Plants that answer these first get more from a free historian than plants that find the gaps afterward.
Start With What You Feed the Historian
A free historian is good news, and TDengine’s Free Tier is a solid way to begin. The next gains come from what enters it. The Capture, Learn, Act framework covers how capture, storage, and AI fit together. To see how raw telemetry becomes usable insight, read From CSV to AI Insight. For why live data matters to every model downstream, see Ground Truth for AI.